Google Gemini API appears to be discontinued. Its website has been unreachable across our last three checks. See similar tools below for alternatives.
Google Gemini API logo

Google Gemini API

A single API key gives access to text generation, multimodal analysis of images, video and documents, image generation and editing with the Nano Banana models, video generation, text-to-speech, spe...

Google Gemini API is the developer interface for building applications on Google's generative models. A single API key gives access to text generation, multimodal analysis of images, video and documents, image…

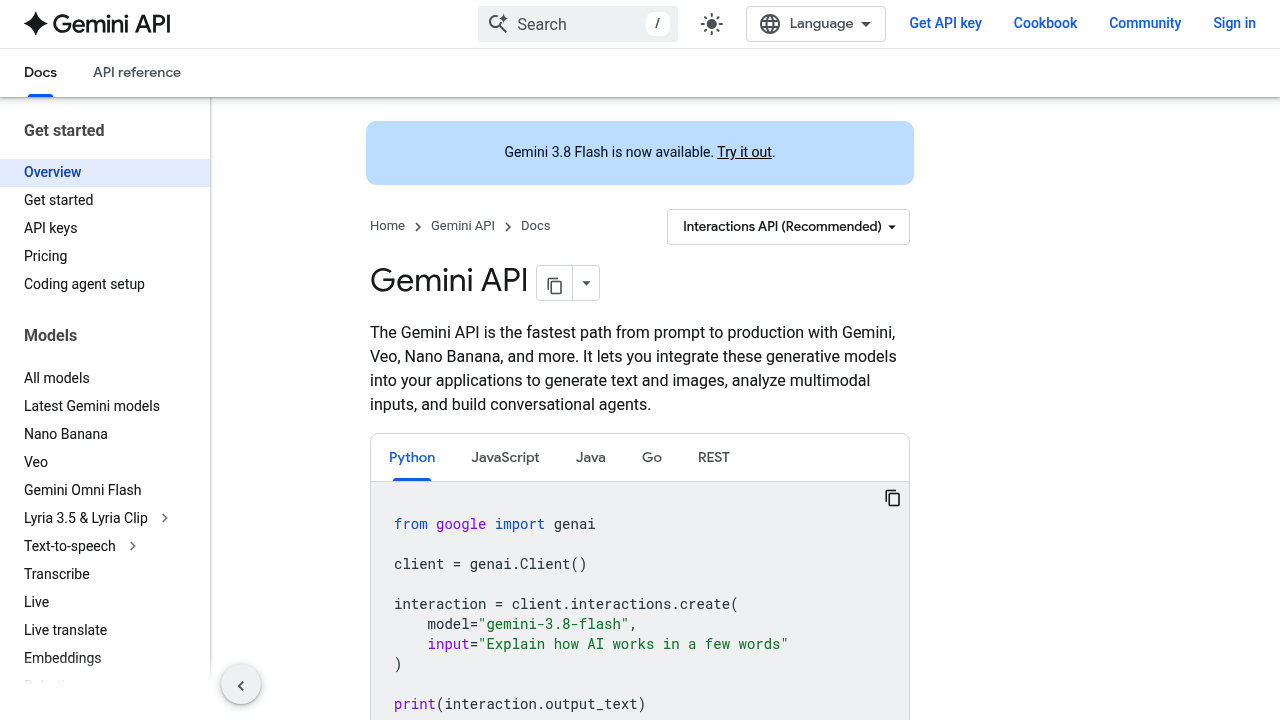
Google Gemini API screenshot

Google Gemini API is the developer interface for building applications on Google's generative models. A single API key gives access to text generation, multimodal analysis of images, video and documents, image generation and editing with the Nano Banana models, video generation, text-to-speech, speech-to-text and agent building. Code samples are provided in Python, JavaScript, Java, Go and plain REST, and developers can choose between the recommended Interactions API and the generateContent API. Long context input lets you pass millions of tokens of unstructured material in one request.

Software engineers, startup founders, data scientists and enterprise platform teams are the main audience. Solo developers can grab an API key and prototype with the cookbook examples, while larger organizations can build production agents and workflows on the same endpoints. Product teams adding summarization, chat or media features to an existing app will find ready-made models for each task. Researchers who need to analyze long documents or hours of video can use the long context support instead of chunking data by hand. Teams working on robotics can also draw on a vision-language model aimed at physical-world reasoning.

Common uses include customer support assistants that answer from company documents, apps that turn voice input into text with speaker detection, studios generating and editing marketing images or short videos, and coding agents that handle long-running engineering tasks. A retail app could describe uploaded product photos, a media company could produce narrated audio with custom voices, and an analytics team could feed in long reports for question answering. Because every capability is exposed over the same API, developers can combine text, image, audio and video steps in one workflow without switching providers.

Frequently asked

6 questions
What can developers build with Google Gemini API?
It supports generating text and images, analyzing multimodal inputs and building conversational agents. Additional models cover video generation, text-to-speech, speech-to-text and robotics reasoning.
Who is Google Gemini API for?
Developers and engineering teams who want to add generative features to their applications are the target audience. Both individual builders prototyping with an API key and enterprises running production agents can use it.
Can I generate images and video through Google Gemini API?
Image generation and editing are available through the Nano Banana 2 and Nano Banana Pro models. A separate model handles video generation and editing.
Which programming languages does Google Gemini API support?
Official examples cover Python, JavaScript, Java and Go, plus direct REST calls with curl. Developers can also pick between the Interactions API and the generateContent API.
What does Google Gemini API require to get started?
You need to create an API key and write code against the endpoints, so some programming experience is expected. It is not a no-code interface for end users.
How much content can Google Gemini API process at once?
Long context input allows millions of tokens, which suits large documents, images and videos. This reduces the need to split material into smaller pieces before analysis.

Reviews (0)

Write review

No reviews yet. Be the first to share your experience.