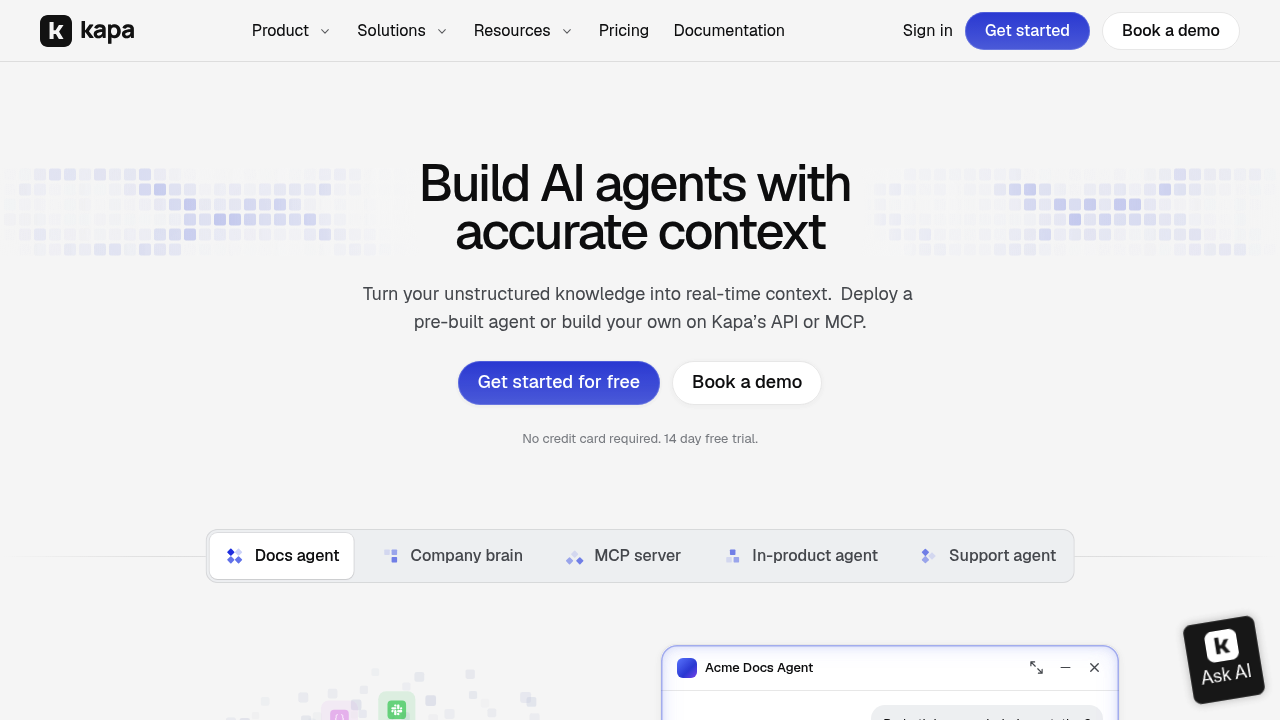
Kapa is a knowledge retrieval API for AI agents. It ingests your documentation and other unstructured knowledge, keeps it current, and returns accurate, cited context that your own agents or Kapa's pre-built agents use to answer questions. Developers can call the Retrieval API, SDKs or a hosted MCP server, while teams that just want an agent live can deploy one as a website widget, Slack bot, Discord bot, Zendesk agent or support form. A 14-day free trial includes 1 index, 5,000 pages crawled, 5,000 retrieval queries and 1,000 answers.
Kapa is aimed at developer relations, documentation, support and product teams at software and hardware companies that field many technical questions. Engineers building their own agents can use retrieval infrastructure with token-efficient context pruning, and support leaders can deploy an agent to deflect tickets without building retrieval themselves. More than 200 companies use it, with customer stories from monday.com, Nokia, Raspberry Pi and Nordic Semiconductor. Enterprise buyers get SOC 2 Type II and GDPR compliance, zero data retention, PII masking, SSO, SCIM and role-based access control.
Typical scenarios include a docs assistant that answers developer questions and cites sources, an in-product agent that handles customer queries and hands off to support by creating a ticket, and an MCP server that gives coding assistants accurate product knowledge. Public sources such as docs, websites, GitHub, YouTube and forums are supported, and the Growth plan adds private and authenticated sources like Confluence, Notion, Zendesk, Salesforce and Drive. Conversation analytics and knowledge gap reports show where content is missing, and agents can be tuned for tone, guardrails, source weighting and languages.