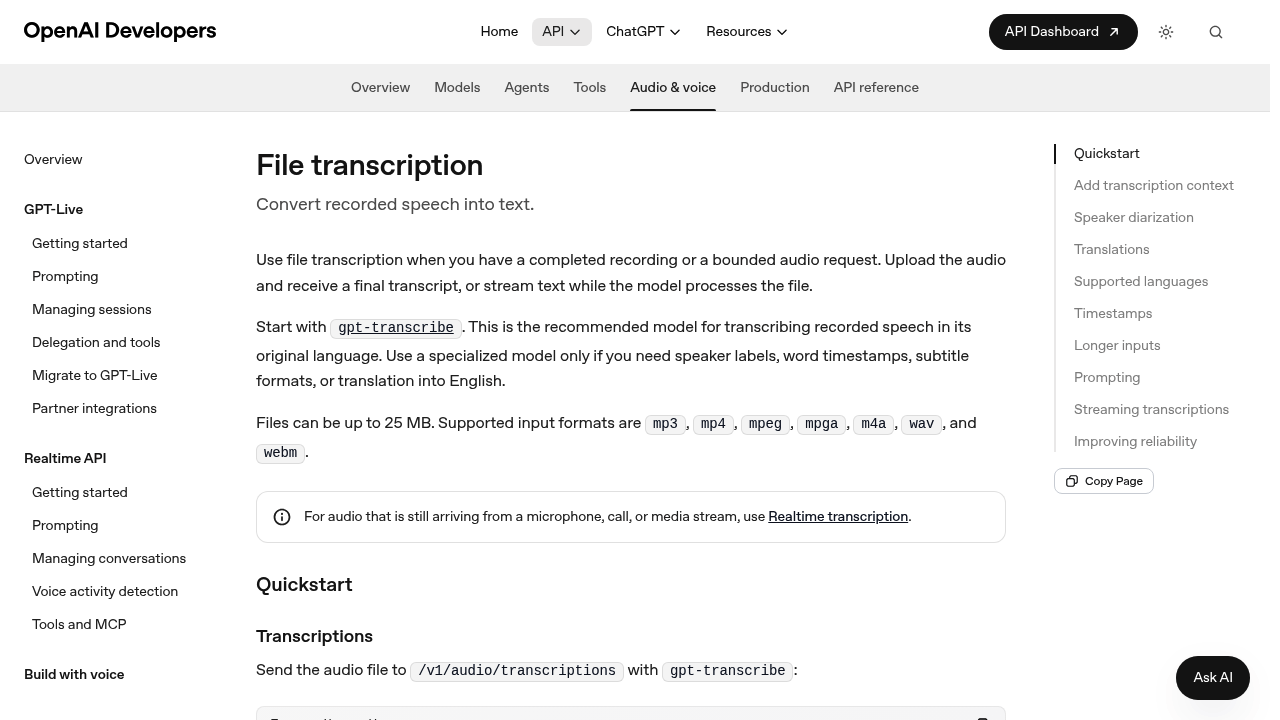
OpenAI Whisper API is the speech-to-text service developers call to convert recorded audio into text. Audio files go in through the audio transcription endpoint, and text comes back, with options to stream transcripts as they are produced and to use specialized speech-to-text features. Whisper supports many languages and can translate spoken audio into English. It is part of the broader OpenAI API, which offers SDKs and a command line tool for building transcription into software.
Software developers and product teams are the target users, including those building meeting recorders, podcast tools, voice notes apps, captioning pipelines and customer call analytics. Data teams use it to turn archives of interviews or support calls into searchable text, and accessibility engineers use it to generate captions. Because access runs through an API key and standard HTTP calls or SDKs, it fits teams with some engineering resources rather than casual end users.
Typical scenarios include transcribing a podcast episode into show notes, converting recorded sales calls into text for analysis, generating subtitles for training videos and capturing lectures for students. A developer can upload an audio file, receive a transcript, then pass it to a summarizer or database. Streaming transcripts suit cases where partial results are needed quickly. The same documentation covers live transcription, live translation, text to speech and voice agents, so a project can start with file transcription and later add real-time voice features. Pricing, rate limits, model choices and error codes are documented alongside the audio guides, which makes it easier for engineers to plan capacity before shipping.