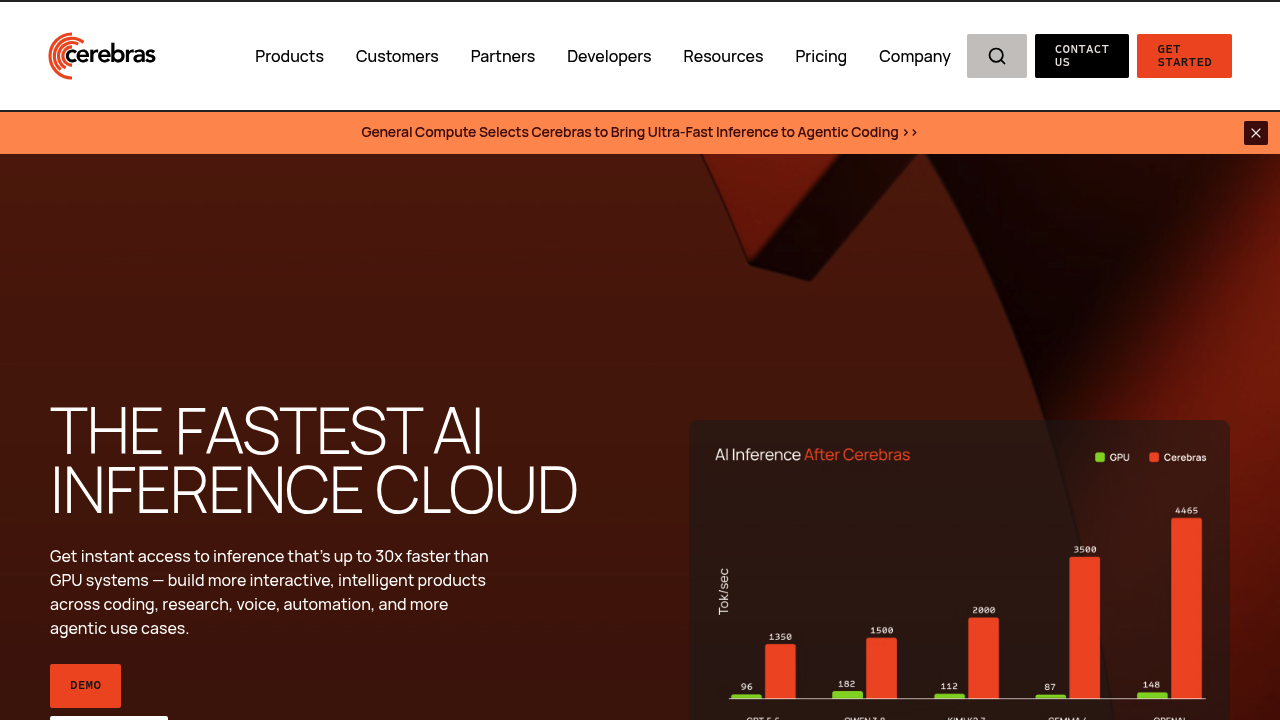
Cerebras Inference is a cloud API for running large language models at very high speed on the Cerebras Wafer-Scale Engine. The company says it is up to 30 times faster than GPU systems, which lets developers add more reasoning inside the same latency budget. The API is compatible with OpenAI's, so moving an app needs just two code changes. A free account gets $5 in credit, the Developer tier is pay-per-token with funds added from $10 and 10x higher rate limits than Free, and Enterprise adds dedicated queue priority and custom model weights.
Cerebras Inference is built for developers and engineering teams shipping latency-sensitive AI products. Startups prototyping agents or voice apps can begin with the free credit, while higher-volume builders move to the Developer tier for faster priority processing. Enterprises that need production-scale throughput, uptime guarantees, dedicated support and custom model weights are directed to sales. Researchers and AI-heavy product groups also use it; GSK and DeepLearning.AI are quoted in customer stories. Teams already on an OpenAI-style SDK will find the switch simple.
A coding product can use fast inference to generate and revise code while the developer waits, which is why General Compute chose Cerebras for agentic coding. A research team can run many reasoning passes to analyze long financial reports within a short response time. A voice app can respond in near real time. An agent developer can chain repeated model calls, a workload DeepLearning.AI points out as a fit. A dashboard builder can generate a financial dashboard from a prompt. Developers can browse the model catalog, pick a model and send requests using the familiar chat API.