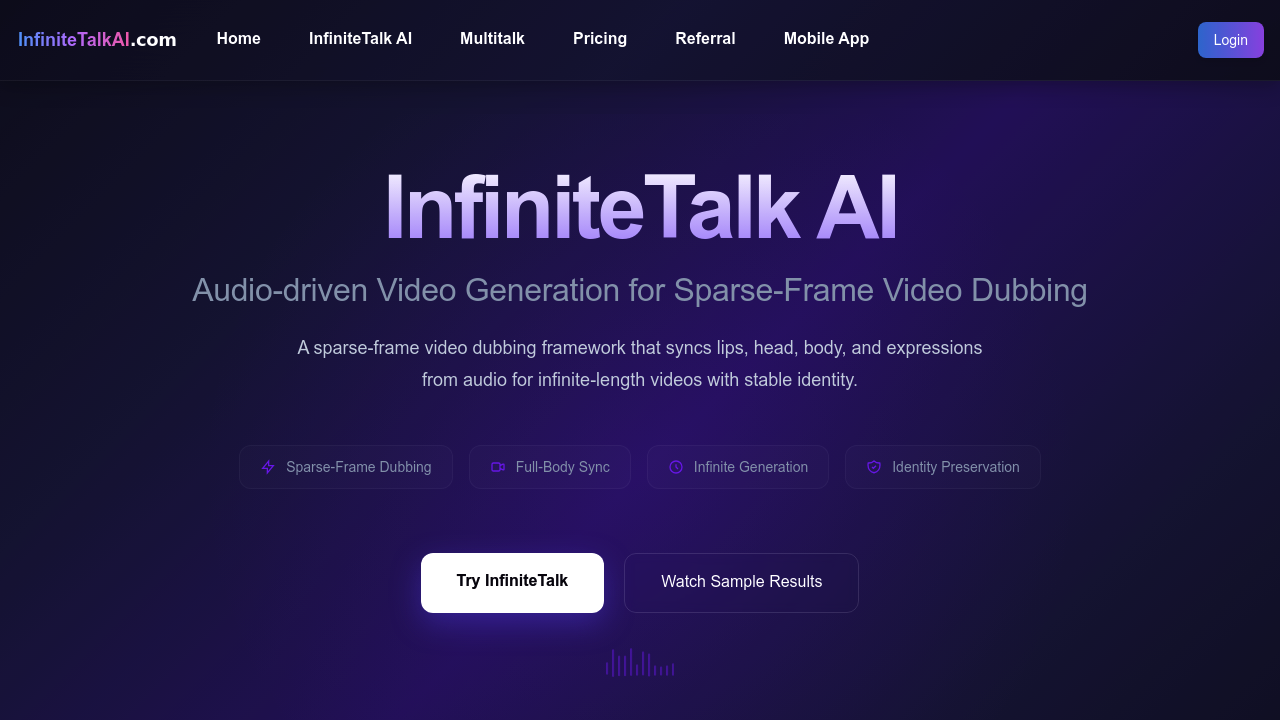
Talking videos get generated from either a single photo and audio file or by dubbing existing footage with new speech tracks. InfiniteTalk AI handles the full synchronization process, matching lip movements to audio while also coordinating head motion, body posture, and facial expressions. The framework processes videos of any length without hitting duration caps, maintaining visual consistency and identity preservation across extended sequences.
The sparse-frame approach means the system doesn't need to process every single frame individually. Instead it identifies key frames and interpolates between them, which helps avoid the visual glitches and stuttering that plague many video generation tools. Memory-based processing tracks what happened in previous frames, so movements flow naturally rather than jumping or resetting. Hand and body artifacts get reduced through this approach, keeping the overall visual stable.
Two modes handle different scenarios. Image-and-audio-to-video takes a static portrait and audio file to create a talking video from scratch. Audio-to-video works with existing footage, replacing the original audio track while adjusting all the visual elements to match the new speech. Text prompts can guide the output, letting users specify particular expressions, emotions, or gestures they want the subject to display during certain parts of the video.
Audio analysis runs deep to achieve tight lip sync. The system emphasizes that source material quality matters considerably. Clear portrait images with good lighting produce better results than blurry or poorly lit photos. Clean audio without background noise or distortion improves lip-sync accuracy. The system supports over 50 languages, handling speech patterns and phonetics across different linguistic structures.
Export happens at three resolution levels: 480p, 720p, and 1080p. Users spend credits to generate videos, with the credit cost presumably varying based on factors like video length and resolution, though specific credit amounts aren't detailed. The service has processed over 1 million videos since launch.
Content creators building YouTube channels, social media accounts, or educational content can generate talking avatars without filming. Video producers dubbing content into multiple languages get synchronized lip movements that match the new audio tracks. Marketers creating personalized video messages at scale can use single portrait images with different audio files. The mobile app extends access beyond desktop workflows, letting users generate or check on video processing from phones or tablets.