#6 in AI Developer Tools Unsloth AI logo

Unsloth AI

A machine learning engineer needs to fine-tune Llama 3 on a single NVIDIA T4 GPU but keeps hitting out-of-memory errors

Standard training frameworks crash halfway through. She tries Unsloth AI's open-source version, which cuts VRAM usage by 60% through handwritten GPU kernels and manually optimized compute steps. The same model that…

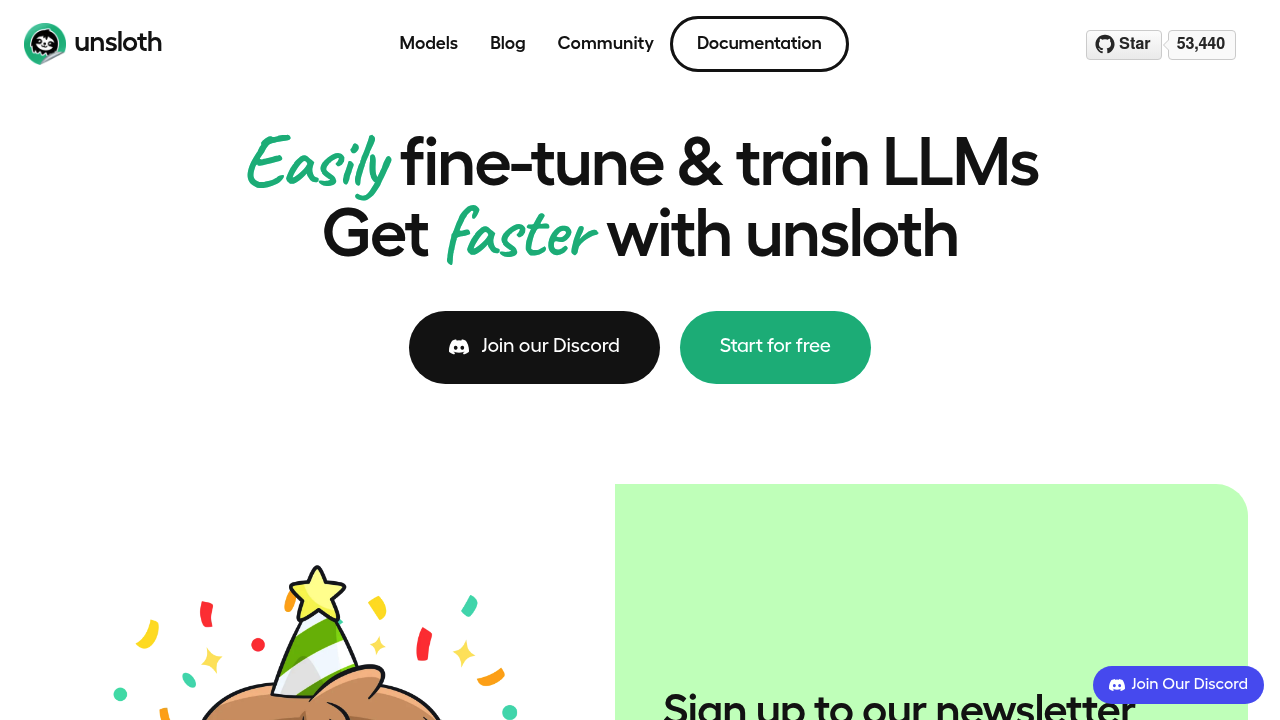
Unsloth AI screenshot

A machine learning engineer needs to fine-tune Llama 3 on a single NVIDIA T4 GPU but keeps hitting out-of-memory errors. Standard training frameworks crash halfway through. She tries Unsloth AI's open-source version, which cuts VRAM usage by 60% through handwritten GPU kernels and manually optimized compute steps. The same model that wouldn't fit now trains successfully. It runs 2x faster than her previous setup.

Unsloth AI speeds up large language model training through low-level optimization rather than hardware upgrades. These tools work by manually deriving compute-heavy math operations and writing custom GPU kernels. This approach delivers 30x faster training than Flash Attention 2 while using 90% less memory. Accuracy improves by 30% in some cases.

Unsloth supports 4-bit and 16-bit LoRA fine-tuning across Mistral, Gemma, and Llama models. You can run it on Google Colab, Kaggle Notebooks, or integrate with Hugging Face and Docker. Hardware compatibility spans NVIDIA GPUs from Tesla T4 to H100, with portability to AMD and Intel GPUs.

A research team running experiments on 8 GPUs uses the Pro tier. Training speed jumps 2.5x while VRAM drops 80% compared to the free version. Multi-GPU support handles their parallel training runs. They process more experiments per day without buying new hardware.

An enterprise AI lab training custom models at scale needs multi-node support and full training capabilities beyond LoRA. The Enterprise tier delivers 30x faster training and 5x faster inference. They run distributed training across multiple nodes with 90% VRAM reduction. Customer support helps them optimize their specific workflows.

The free tier works great for single-GPU setups. Multi-GPU support is coming but isn't available yet. That limitation matters if you're running parallel experiments today. The Pro tier caps at 8 GPUs, which won't work for massive distributed training operations. Inference features are still developing, so don't expect production-ready deployment tools yet.

Support for TTS, BERT, and FFT models expands beyond standard language model fine-tuning. Unsloth handles embedding fine-tuning and faster MoE training. Context length extends 7x longer with GRPO. These features matter if your work goes beyond basic text generation.

Unsloth fits researchers and ML teams who train models regularly. It is built for situations where memory constraints block progress or training time eats up project budgets. Companies fine-tuning models for specific domains see immediate returns.

It doesn't fit teams who need plug-and-play solutions with no technical setup. You're writing code and configuring training runs. If you're just using pre-trained models through APIs, this won't help. Teams without GPU access can't use it at all since it requires NVIDIA hardware at minimum.

The speed gains compound with scale. A single training run that took 10 hours might finish in 5 with the free tier or 4 hours with Pro. Those hours add up across dozens of experiments. The VRAM savings let you train larger models on existing hardware instead of upgrading to expensive GPUs.

Skip this if you're not actively training or fine-tuning models. Getting started demands ML engineering knowledge. But if memory errors or slow training speeds currently block your work, this optimization approach solves real bottlenecks.
Unsloth AI alternatives

See all →

Frequently asked

7 questions
How much faster is Unsloth AI compared to standard training?
A machine learning engineer training Llama 3 with the free version sees 2x faster training compared to standard frameworks, cutting a 10-hour run down to 5 hours. An ML team on the Pro tier gets 2.5x speed improvements with 80% VRAM reduction across their 8-GPU setup. Enterprise users running distributed training hit 30x faster speeds than Flash Attention 2, turning multi-day training jobs into hours. The speed multiplies with scale, so teams running dozens of experiments save weeks of compute time. Memory optimization happens through handwritten GPU kernels rather than hardware upgrades.
Does Unsloth AI have a free version?
The open-source version runs free on single GPUs with 2x speed boost and 60% VRAM reduction. A researcher fine-tuning Mistral on Google Colab uses this tier without paying anything, getting full support for 4-bit and 16-bit LoRA. Multi-GPU support isn't available yet in the free tier, so teams running parallel experiments need to wait or upgrade. Pro and Enterprise tiers require contacting for pricing but deliver 2.5x to 30x faster training with expanded GPU support. Free tier covers Mistral, Gemma, and Llama models with Hugging Face and Docker integration.
What GPU do I need for Unsloth AI?
A data scientist with an older Tesla T4 GPU can run Unsloth without upgrading hardware, since it supports NVIDIA cards from T4 through H100. The VRAM reduction means models that wouldn't fit on a T4 now train successfully through optimized memory usage. Teams with AMD or Intel GPUs can use Unsloth since it's portable across hardware beyond NVIDIA. You need some GPU access though, cloud or local. Researchers without any GPU hardware can't use Unsloth at all since it requires compute resources for model training.
Can Unsloth AI handle multi-GPU training?
An ML engineering team with 6 GPUs uses the Pro tier to run parallel training jobs with enhanced multi-GPU support up to 8 GPUs. The free tier currently supports only single GPU, with multi-GPU coming soon but not available yet for open-source users. Enterprise customers running massive distributed operations get multi-node support across dozens of GPUs with 32x faster speeds than Flash Attention 2. Pro tier caps at 8 GPUs, so research labs needing 16 or 32 GPU setups must go Enterprise. Multi-GPU users see training speeds multiply while VRAM drops 80-90% across their hardware.
What models does Unsloth AI work with?
A developer fine-tuning Llama 3 for domain-specific tasks uses Unsloth with full support for Mistral, Gemma, and Llama 1, 2, and 3 models. Beyond standard language models, it handles TTS, BERT, FFT, embedding fine-tuning, and faster MoE training. An NLP researcher working with 4-bit and 16-bit LoRA configurations switches between model architectures without compatibility issues. Context length extends 7x longer with GRPO for teams needing extended conversations. Unsloth doesn't support every model architecture, focusing on popular open-source LLMs rather than proprietary or niche models.
When shouldn't I use Unsloth AI?
A product manager using ChatGPT through an API doesn't need Unsloth since it's built for training and fine-tuning, not consuming pre-trained models. Developers wanting plug-and-play solutions without writing training code won't find ready-made interfaces here. Inference features are still developing, so teams needing production-ready deployment tools should wait or look elsewhere. Companies without ML engineering resources to configure training runs and optimize hyperparameters will struggle with the technical setup. Unsloth solves memory and speed bottlenecks during training, not general AI application development.
How much VRAM does Unsloth AI save?
A researcher hitting out-of-memory errors on a 16GB GPU switches to Unsloth's free tier and cuts VRAM usage by 60%, fitting models that previously crashed. Teams on Pro tier see 80% VRAM reduction, training larger models on the same hardware without expensive upgrades. Enterprise users get 90% VRAM reduction compared to Flash Attention 2, running models that would need multiple high-end GPUs on fewer cards. The memory savings come from manually optimized compute steps and handwritten GPU kernels rather than compression tricks. A model needing 40GB of VRAM might run in 8GB with Pro tier optimizations.

Traffic

Estimated monthly website visits · last 9 months

1.5M visits/mo
Monthly visits
1.5M
↑ 47.7% MoM
Global rank
#57,929
US #62,743
Category rank
#6
AI Developer Tools
1.6M 1.3M 1M 780K 517K Dec 2025: 517K visits Dec 2025 Jan 2026: 574.8K visits Jan 2026 Feb 2026: 698.3K visits Feb 2026 Mar 2026: 1.3M visits Mar 2026 Apr 2026: 1.6M visits Apr 2026 May 2026: 1.1M visits May 2026 Jun 2026: 1.2M visits Jun 2026 Jul 2026: 1M visits Jul 2026 Aug 2026: 1.5M visits Aug 2026

Reviews (0)

Write review

No reviews yet. Be the first to share your experience.