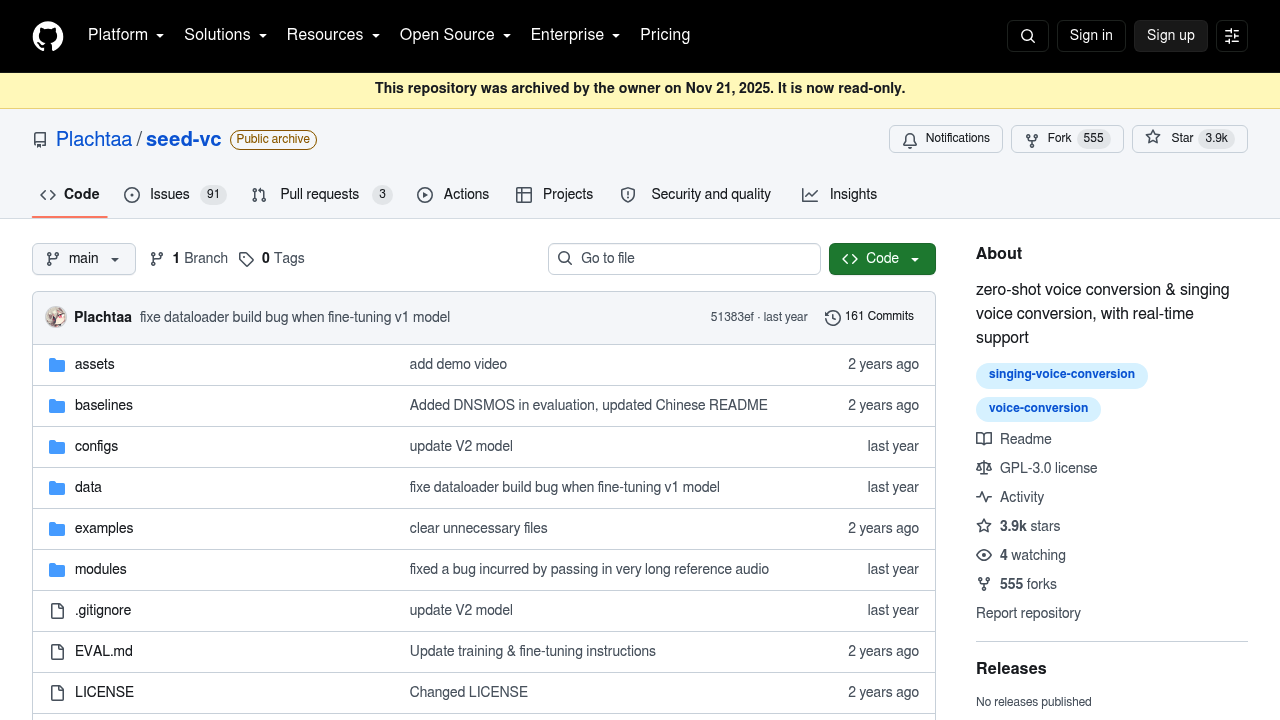
Seed-VC is an open-source voice conversion project that changes one speaker's voice into another without per-speaker training. Given a reference recording of 1 to 30 seconds, it converts speech or singing to match that voice, and it supports real-time conversion with about 300ms of algorithm delay plus roughly 100ms on the device side. Four models have been released for different purposes, including a small model suited to real-time use, a larger offline model, a singing voice model and a v2 model for voice and accent conversion. The code is free to download from GitHub.
Seed-VC is built for machine learning engineers, speech researchers and technically comfortable creators who can install Python dependencies and run models locally on Windows, Mac with Apple Silicon or Linux. Developers who want to fine-tune on a specific speaker can do so with very little data: the project cites a minimum of one utterance per speaker and about two minutes of training on a T4 GPU. Note that the repository was archived by its owner on November 21, 2025, so it is read-only and no longer actively developed.
Documented uses include live voice conversion for online meetings, gaming and live streaming, converting singing voice for music experiments, and changing accent in speech recordings with the v2 model. Researchers use the evaluation material to compare it with baseline voice conversion systems, and developers wrap the Python inference scripts or the included web apps into their own pipelines. Command-line inference takes a source recording, a reference recording and options such as diffusion steps and pitch shift, and checkpoints download automatically the first time inference runs.