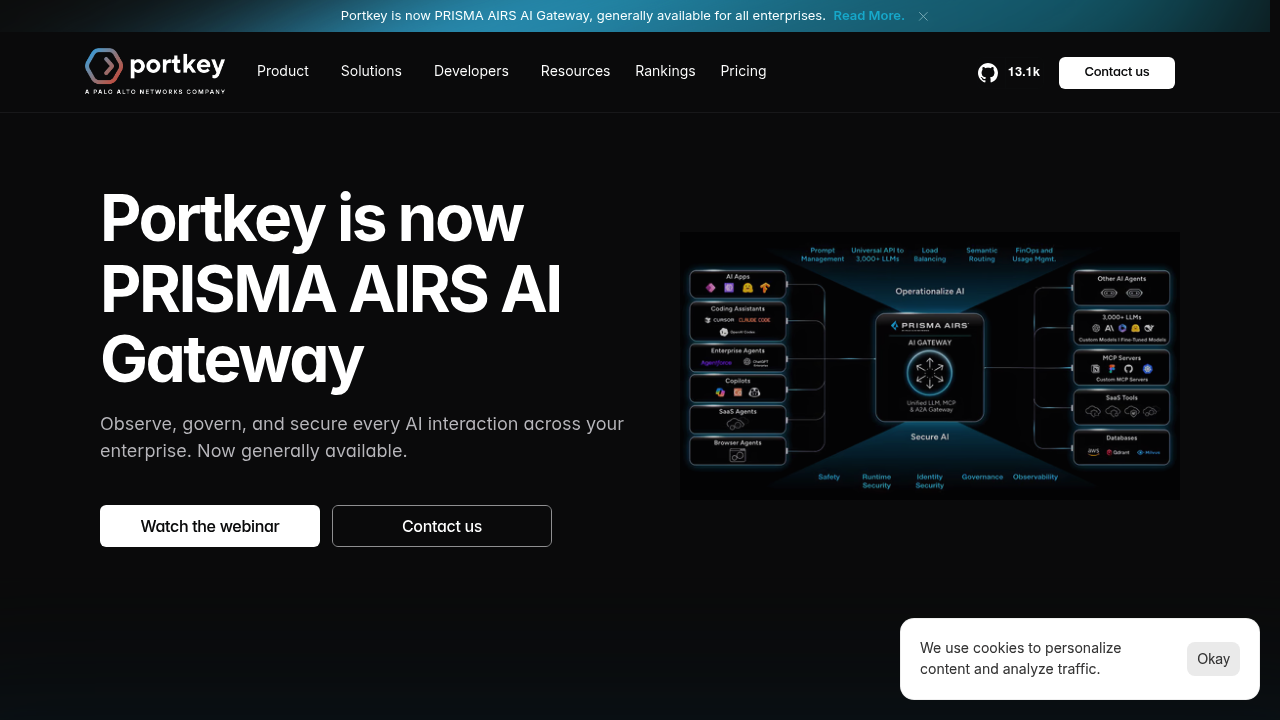
Portkey puts a single API in front of more than 1,600 language models and wraps it with the controls a production AI team needs. The gateway handles fallbacks, load balancing and retries, while observability records logs, traces, feedback and custom metadata for each request. Guardrails, prompt management with versioning, and simple or semantic caching sit on the same platform. A Developer plan is free forever with 10k recorded logs a month, and the Production plan costs $49 per month for 100k logs, 30-day log retention, alerts and role-based access control. Enterprise pricing is custom.
Portkey fits AI engineers, platform teams and machine learning leads who ship LLM-powered products and need visibility into cost, latency and failures. Startups can prototype on the free Developer plan before moving to Production, and larger organizations get SSO, granular budget and rate limits, private cloud deployment and compliance coverage including SOC2 Type 2, GDPR and HIPAA. Teams that manage many model keys across departments benefit from service account keys and per-use-case cost tracking. Product managers and prompt authors can edit versioned templates without touching application code.
Typical setups include routing requests between providers so an outage on one model falls back to another, caching repeated test calls in CI pipelines to cut spend, and tracing multi-step agent workflows end to end. Teams also apply guardrails to filter model output, set budgets for each department, expose approved MCP tools to agents, and keep a pricing reference for model costs. One customer described tracking costs per use case and making sure keys were used correctly across more than 25 GenAI use cases. Integration takes a few minutes by swapping the base URL in an existing SDK.