Hugging Face Inference Endpoints logo

Hugging Face Inference Endpoints

Hugging Face Inference Endpoints is a managed service for putting AI models into production without running the infrastructure yourself.

You import a model from the Hugging Face Hub or pick one from a catalog of ready-to-deploy models, and a dedicated endpoint is created with autoscaling and built-in logs and metrics. Engines include vLLM, SGLang,…

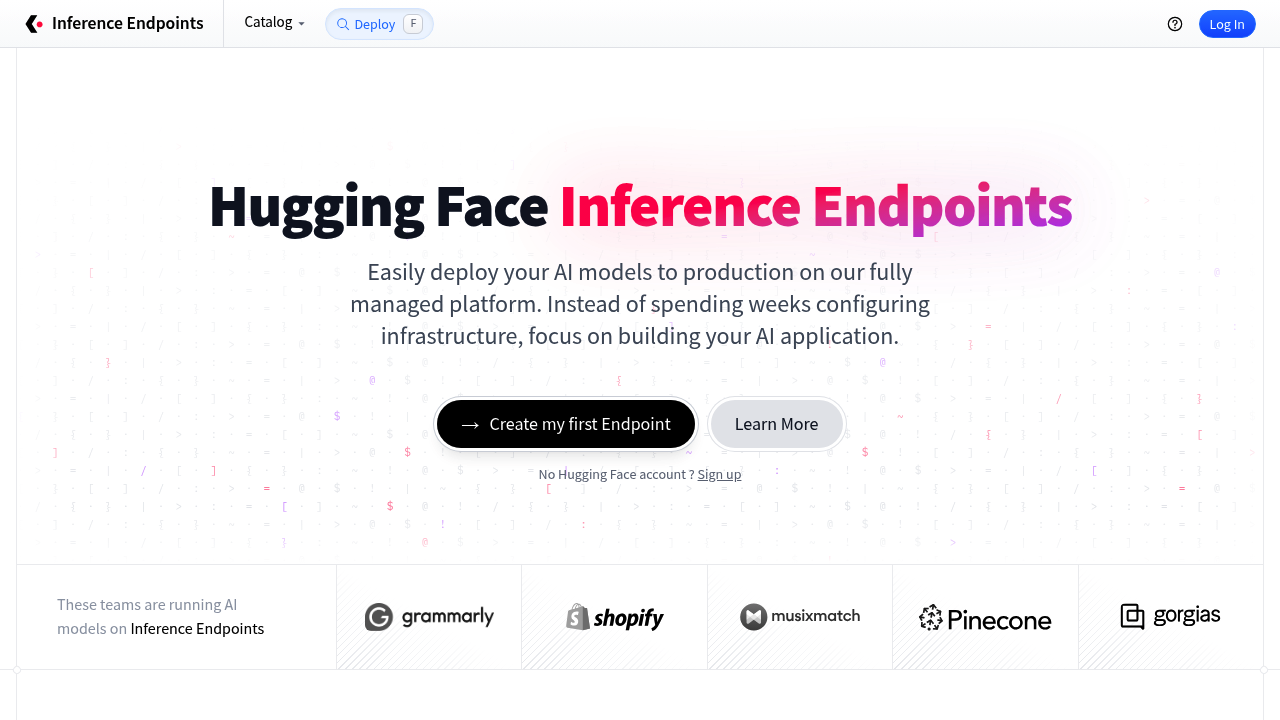
Hugging Face Inference Endpoints screenshot

Hugging Face Inference Endpoints is a managed service for putting AI models into production without running the infrastructure yourself. You import a model from the Hugging Face Hub or pick one from a catalog of ready-to-deploy models, and a dedicated endpoint is created with autoscaling and built-in logs and metrics. Engines include vLLM, SGLang, llama.cpp, TGI and TEI, or you can bring a custom container. The Self-Serve plan is pay-as-you-go, billed per minute and monthly, starting from $0.06 per hour, and Enterprise adds volume pricing, uptime guarantees and SLAs.

It is built for machine learning engineers, data scientists and product teams who have a model and need a reliable API for it. Startups can avoid hiring dedicated infrastructure staff, since Kubernetes, CUDA versions and VPN setup are handled for them. Larger companies can move to Enterprise for custom annual contracts and dedicated support. Teams already working with Hugging Face models benefit most, because weights download quickly and securely from the Hub.

Common scenarios include serving a text classification model behind a production API, hosting an image generation model such as Stable Diffusion for an app, and running large language models on dedicated GPUs for a customer-facing feature. A team can set a custom handler to define its own inference pipeline, then let autoscaling absorb traffic spikes and scale down to save compute costs. Developers can also ask their coding agent to spin up an optimized endpoint for any Hub model in a single prompt. Listed examples show hourly rates from about $0.067 for small models up to $40 for the largest ones, depending on the GPU or CPU chosen.
Hugging Face Inference Endpoints alternatives

See all →

Frequently asked

6 questions
How do Inference Endpoints deploy a model?
You import a model from the Hugging Face Hub or choose one from the hand-picked catalog, then deploy it with one click. The service provisions fully managed infrastructure and exposes the model as an endpoint. Engines such as vLLM, SGLang, llama.cpp, TGI and TEI are supported.
Who should use Inference Endpoints?
Machine learning engineers, data scientists and application teams that need a production endpoint without maintaining servers. Companies such as Grammarly, Shopify, Musixmatch, Pinecone and Gorgias are listed as users. Enterprises can add SLAs and dedicated support.
Can I run a custom inference pipeline?
Custom containers are supported, so a team can package its own serving code. One customer describes defining a complete custom interface from model to inference process in a couple of hours. Standard engines are available when no customization is needed.
How does pricing work for Inference Endpoints?
The Self-Serve plan is pay-as-you-go, charged per minute and billed monthly, with rates starting as low as $0.06 per hour. Featured models range from about $0.067 to $40 per hour depending on hardware. Enterprise offers lower marginal costs at volume under custom annual contracts.
What does it cost to keep a large model running?
Large language models on high-end GPUs sit at the top of the hourly range, with featured examples at $20 to $40 per hour. Autoscaling reduces compute when traffic drops, which limits idle spend. Costs therefore track the hardware and uptime you choose.
How do I get started with Inference Endpoints?
Sign up for a Hugging Face account, then click to create your first endpoint and select a model. Documentation is available for setup details. Coding agents can also create an endpoint for any Hub model from a single prompt.

Reviews (0)

Write review

No reviews yet. Be the first to share your experience.