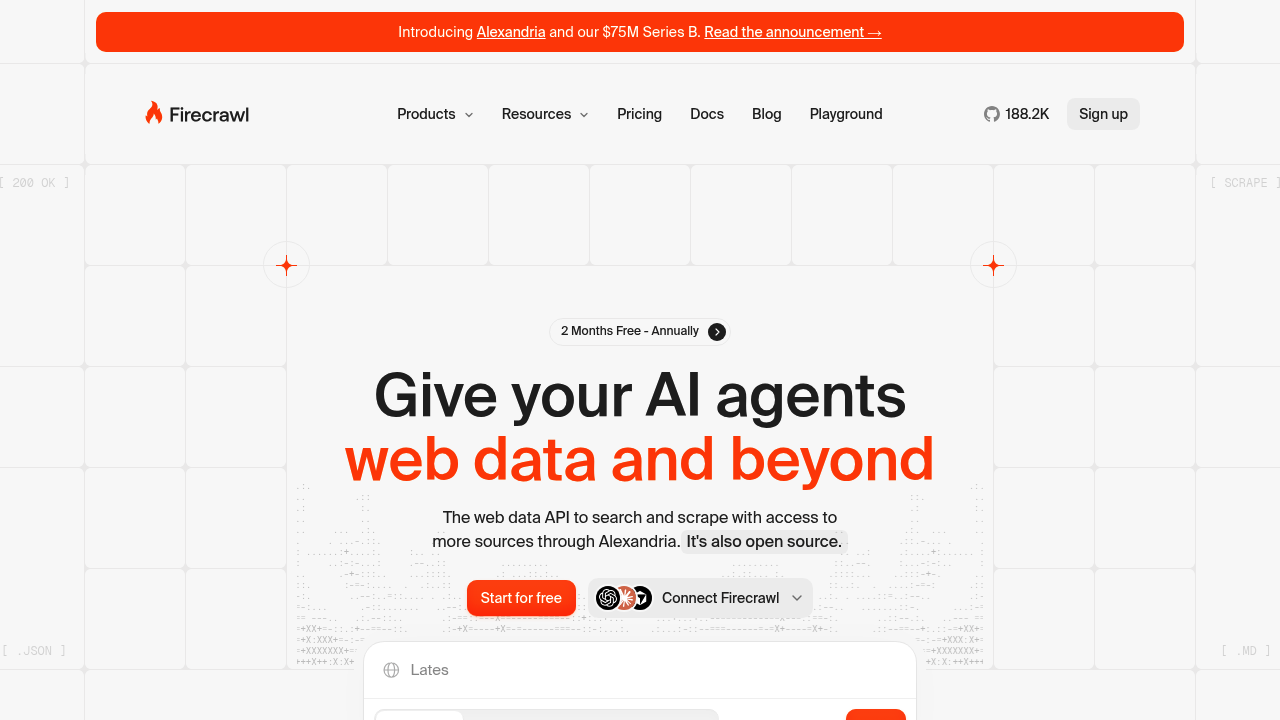
Firecrawl is a web data API that gives AI agents and applications clean content from the live web. Its endpoints search the web and return full page content, scrape single pages into markdown, JSON or screenshots, crawl and map whole sites, and interact with a page through prompts or code. JavaScript rendering, smart waiting and media parsing are handled for you, and navigation, footers and ads are stripped to save tokens. Plans start with a free tier of 1,000 credits per month, and Hobby costs $19 per month or $16 billed yearly for 5,000 credits.
Developers building agents, retrieval pipelines and research tools are the main audience, along with data teams that need structured web data without maintaining headless browsers. Higher plans scale from Standard at 100,000 credits per month to Growth and Scale, with enterprise options adding zero data retention and SSO. More than 150,000 companies use it, and the code is open source.
A typical workflow installs the Python or Node.js SDK, passes an API key and scrapes a URL, then feeds the markdown to a language model. Agent builders connect it through MCP or the CLI with a single command. Teams use search to gather sources for a research agent, crawl documentation sites to build a knowledge base, and use the interact endpoint to click through a shop, search for a product and read the result. The vendor reports 96 percent coverage on a 1,000-URL benchmark and a P95 latency of 3,387 milliseconds. Failed scrapes that return no result are not charged, and pay-as-you-go credits can be added on paid plans.