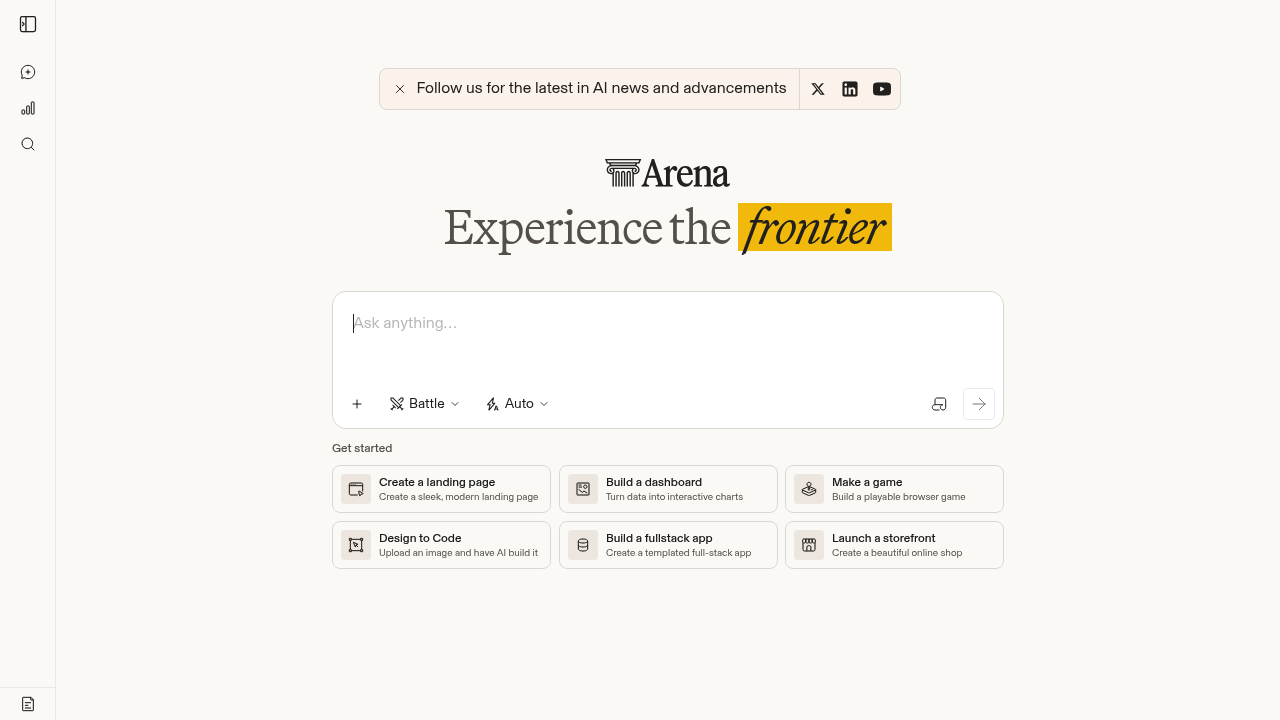
LMArena, now branded Arena, is a place to chat with, compare and vote on AI models. Visitors send a prompt, see answers from different models and pick the better one, and those votes feed a public leaderboard covering language, image and code models. Beyond head-to-head battles, it offers prompt starters for building a landing page, a dashboard, a browser game or a full-stack app, so people can judge models on practical output. The result is a community-driven ranking based on real-world evaluation rather than fixed benchmarks alone.
Arena serves developers and product teams deciding which model to build on, researchers who track how models compare, and curious users who want to try several systems without separate accounts. Students and writers can test which assistant handles their kind of question best. Model providers watch the leaderboard to see how their releases rank against rivals. Because the ranking comes from voting by the community, it reflects what ordinary users actually prefer, which is useful context for anyone selecting a model for an app or workflow.
A developer can submit the same coding task to two anonymous models and vote on which result works better, or use a starter such as design-to-code by uploading an image and having AI build it. A founder comparing assistants for a customer-facing feature can read the leaderboard to shortlist candidates, then run battles on the prompts that matter to the business. Researchers follow rankings across text, image and code categories to see how new releases perform. Anyone can also generate a quick storefront, dashboard or playable game to see how models handle open-ended creative requests. Responses from third-party AI can be inaccurate, so important outputs need checking.